
Please rotate your device
To continue exploring this website, please rotate your device to a vertical orientation

DFlash: 3x faster LLM inference
DFlash beats EAGLE's ~2x speedup ceiling with parallel token prediction. Baseten's implementation hits 3x speedups on Qwen3-8B, 10-30% faster than vLLM.
- Authors
- Last updated
- Originally published

By design, LLMs today only output one token at a time. As a result, speculative decoding (SpecDec) has become one of the most effective ways to improve LLM inference latency: a smaller draft model proposes tokens that the target model verifies in parallel, yielding 2x+ speed improvements depending on proposal acceptance rates.
EAGLE (original, EAGLE-2, and now EAGLE-3) emerged as one of the most popular SpecDec techniques, using the target model's hidden states to predict draft tokens with better acceptance rates than earlier approaches. But EAGLE is autoregressive; each predicted token requires its own forward pass from the draft model, which in practice often caps its speedups at roughly 2x as it lets errors accumulate across forward passes.
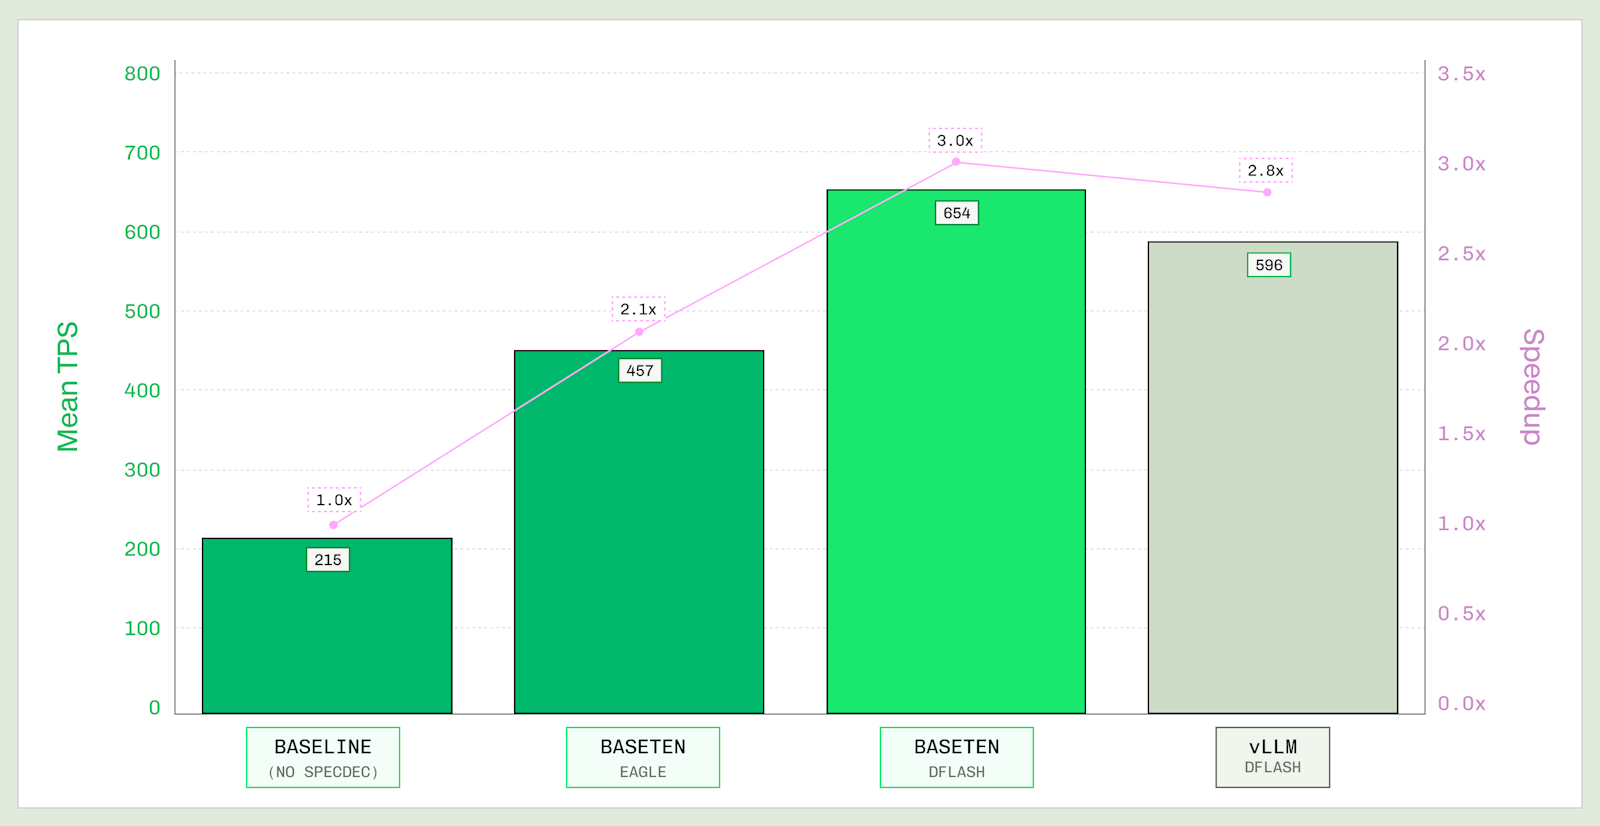
DFlash was introduced in February 2026 (paper, code) to push past the ceiling that autoregressive drafting imposes on SpecDec speedups. A single DFlash forward pass completes faster than the entire EAGLE draft phase, while predicting several more tokens. In practice, we see that translates to a 50% speed bump: on Qwen3-8B on a single B200, Baseten's DFlash implementation delivers ~3x speedups across various benchmarks (in terms of inference latency and throughput), compared to 2x with EAGLE.
This post covers how DFlash works, how Baseten's implementation differs from vLLM and SGLang, training details, and full benchmark results, including inference latency and throughput across GSM8k, MATH-500, and NVIDIA’s Nemotron post-training dataset.
DFlash: Block diffusion for speculative decoding
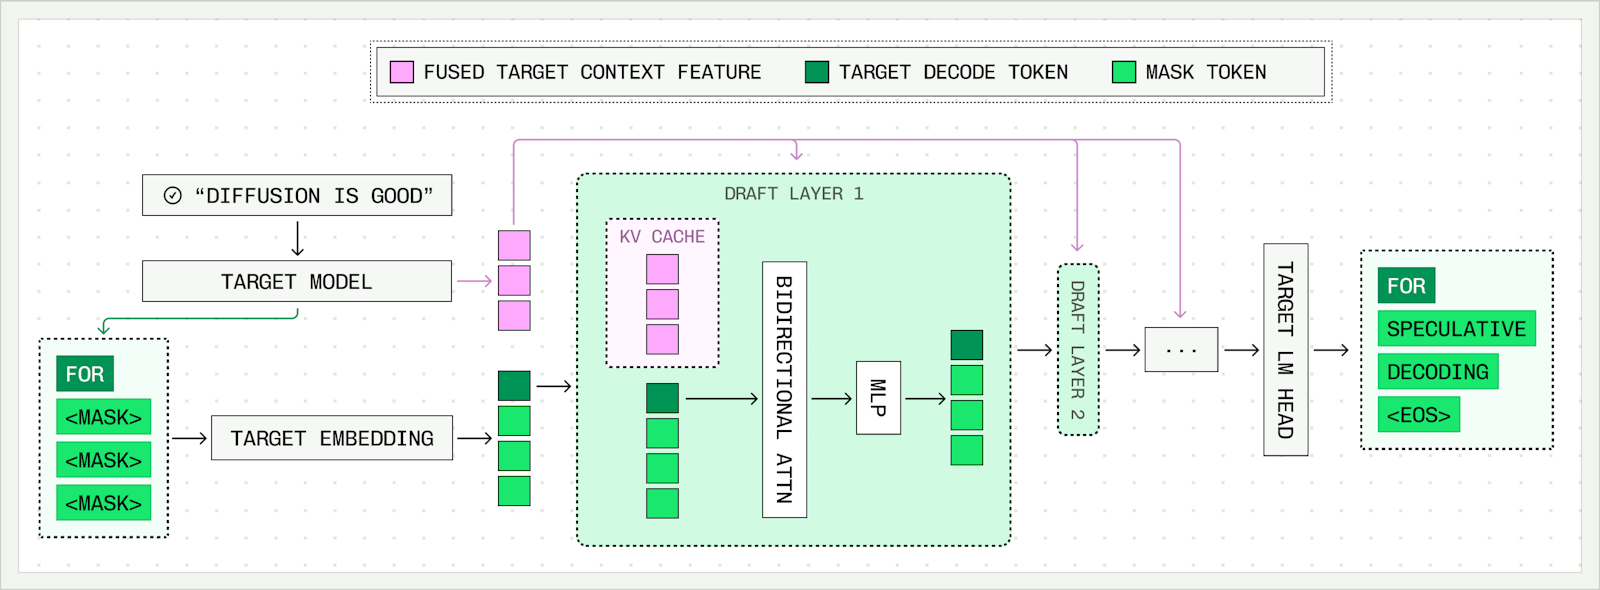
DFlash aims to bridge the quality of autoregressive decoding with the speed of diffusion LLMs. Like EAGLE, DFlash uses the hidden states of the target model as input features, as they provide very rich data representations aligned with the target model. But unlike EAGLE, DFlash:
Predicts multiple (γ) tokens in parallel in a single forward pass by using bidirectional attention
Allows for a much deeper draft model without sacrificing speed
Although a single forward pass for the larger DFlash draft model might be 2-4x slower than a single forward pass for EAGLE (depending on model sizes), DFlash predicts 8-16 tokens at once, while EAGLE could only predict 1. That means that despite the larger draft model, a single DFlash forward pass is faster than the entire EAGLE draft phase, while also predicting several more tokens. The larger model size also allows DFlash draft models to learn more and produce higher-quality drafts.
The DFlash model looks like this:
DFlash in the Baseten Inference Stack
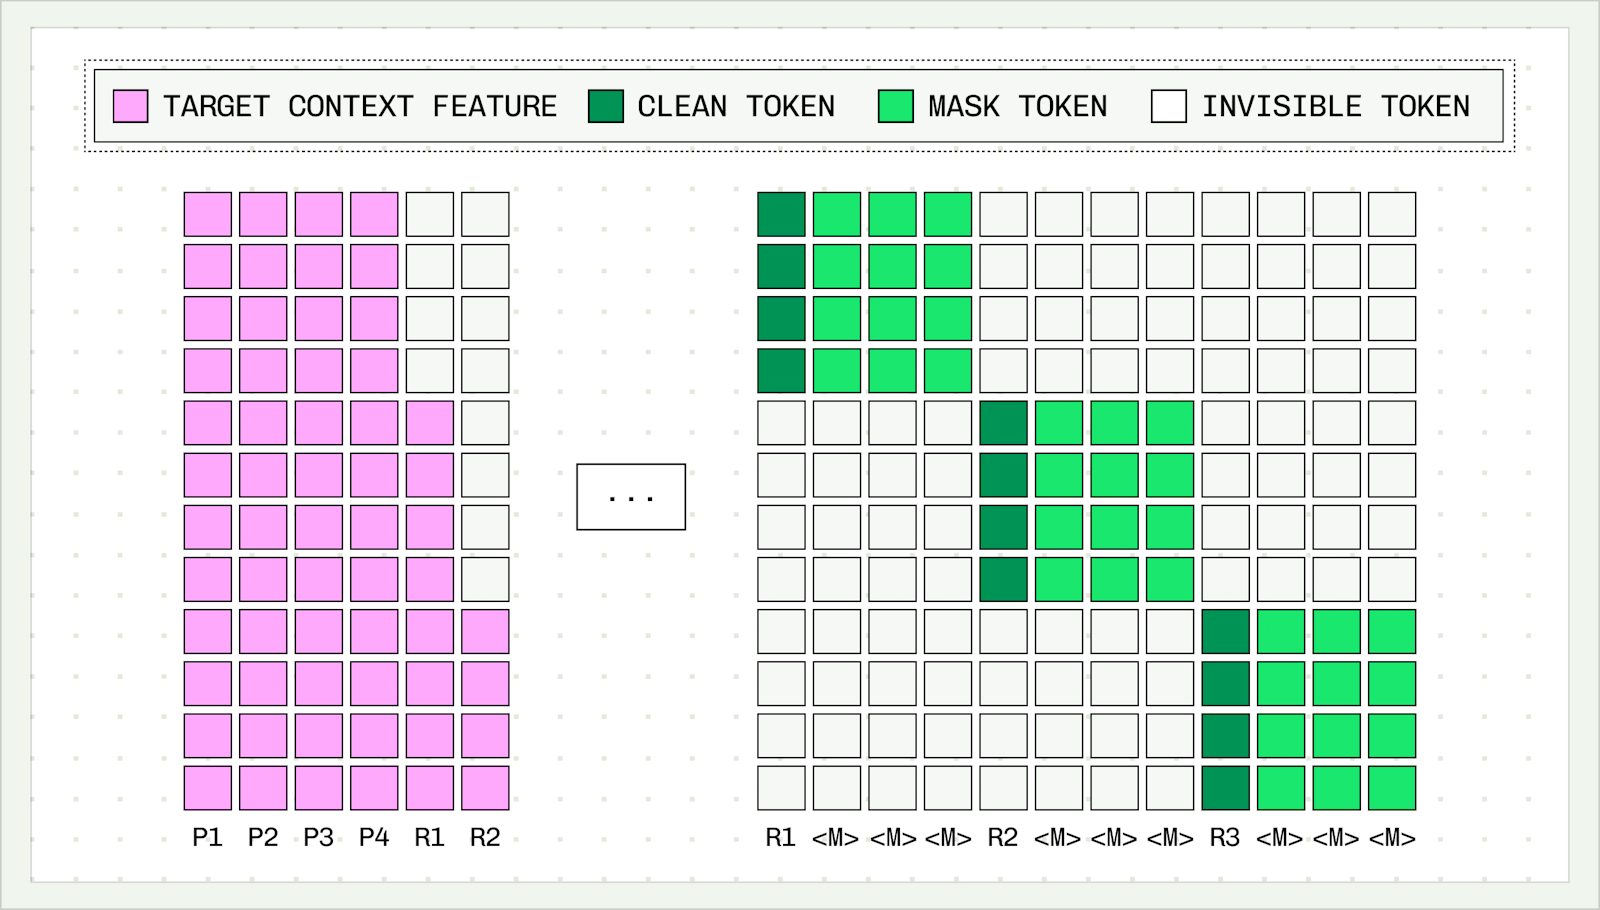
For drafting the new tokens, DFlash creates a block of size block_size (a parameter), with the first token being the last valid token (either the last context token or the last accepted token), and the rest being mask tokens. Then, similar to masked language modeling, the DFlash model proceeds to unmask the mask tokens.
In practice, we take the hidden states from 5-6 evenly spaced layers of the target model. The same hidden states are passed through all layers of the DFlash model. These are projected to construct the KV cache for each layer.
We have failed to find a faster DFlash implementation than our own. To make DFlash so fast, we tested each backend to leverage the fastest one and implemented a custom forward pass mechanism to prepare the KV cache and produce output tokens. We also support guided decoding.
Results: DFlash speed improvements on 3 benchmarks
To assess inference latency and throughput improvements from using DFlash, we tested our implementation with Qwen3-8B across three benchmarks. We used GSM8k and MATH-500 because they were used in the original DFlash paper (making the results directly comparable), and we added a diverse prompt dataset (NVIDIA’s Nemotron post-training dataset covering science, coding, and general chat) to test generalization beyond math.
Our DFlash implementation outperforms both EAGLE and other DFlash backends (vLLM, SGLang) across all three benchmarks. We don't report the numbers for SGLang here since we could not reproduce reliable results (more details below), but even after cleaning up the output sequences post-hoc, both our imlementation and vLLM were faster that SGLang.
GSM8k (arithmetic reasoning)
The GSM8k benchmarks were conducted at concurrency 16 on a single B200 GPU. Throughput results (higher is better):
| Setting | Speedup in TPS | TPS (mean) | TPS (median) | TPS (p95) |
|---|---|---|---|---|
| Baseline TRT-LLM (no SpecDec) | 1.00x | 215.25 | 216.28 | 224.76 |
| Baseten EAGLE (best setting) | 2.12x | 456.86 | 457.23 | 512.88 |
| Baseten DFlash (best setting) | 3.04x | 654.16 | 658.42 | 792.94 |
| vLLM DFlash (best setting) | 2.77x | 596.03 | 587.20 | 772.13 |
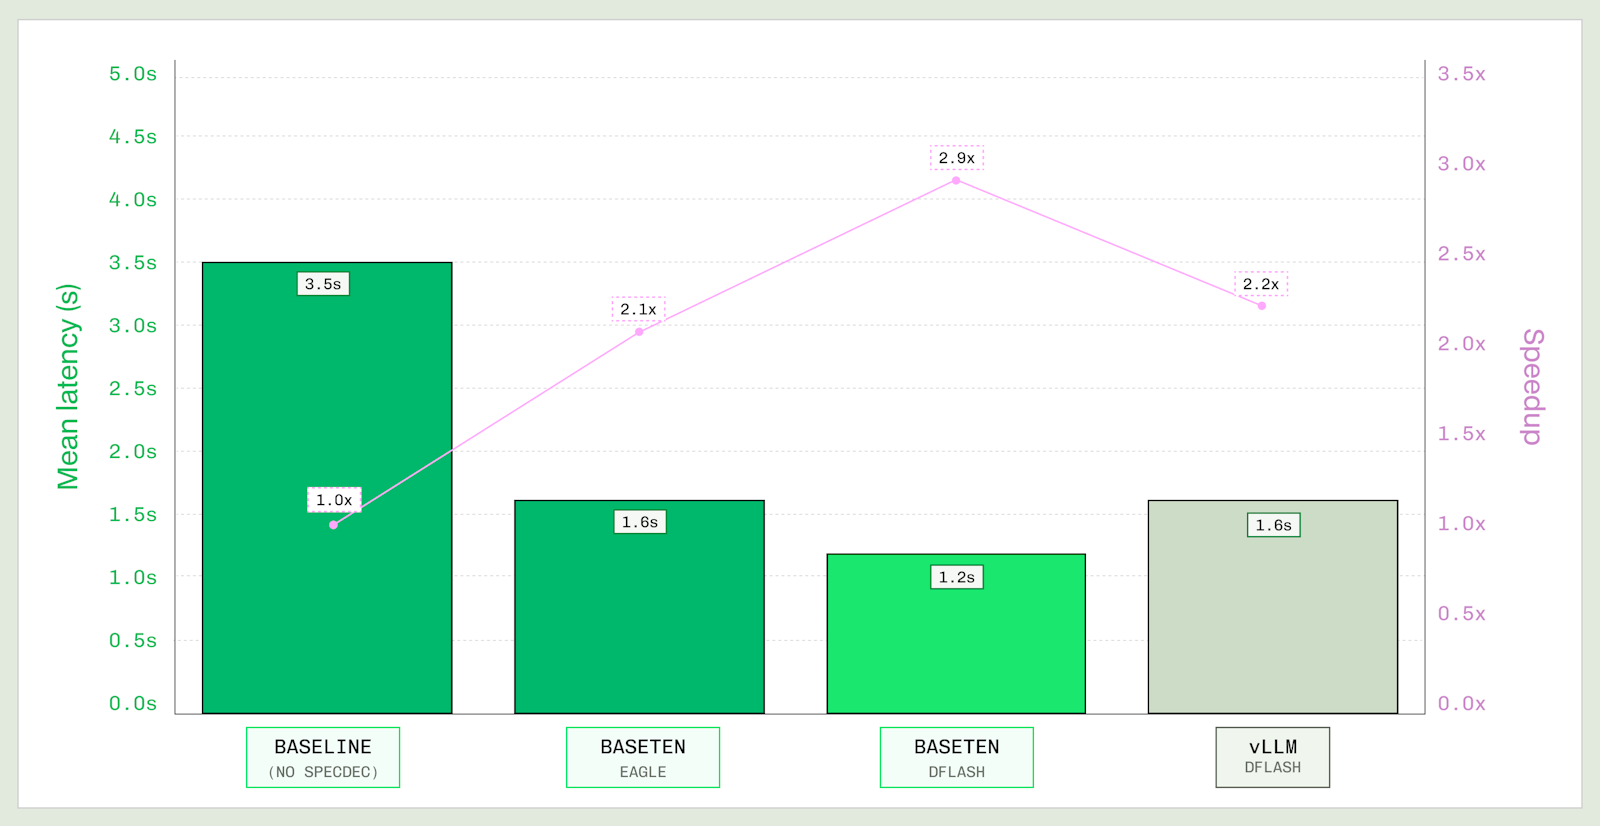
And latency results (lower is better):
| Setting | Speedup latency | Latency (mean, sec) | Latency (median, sec) | Latency (p95, sec) |
|---|---|---|---|---|
| Baseline TRT-LLM (no SpecDec) | 1.00x | 3.513 | 2.318 | 11.244 |
| Baseten EAGLE (best setting) | 2.13x | 1.650 | 1.120 | 5.144 |
| Baseten DFlash (best setting) | 2.84x | 1.222 | 0.782 | 3.818 |
| vLLM DFlash (best setting) | 2.16x | 1.629 | 0.995 | 5.744 |
SGLang also supports DFlash, however, in our evaluation, SGLang produced unreliable results due to a high rate of looping outputs. In these cases, a sequence of tokens near the end of the response was repeated until generation completed.
Because these repeated tokens did not represent meaningful generation, the resulting outputs were unsuitable for evaluation and resulted in unusually high acceptance rates and throughput. This made the aggregate statistics unrepresentative of usable generation quality. Although we filtered out these samples, this altered the output length distribution and biased our data towards shorter and faster generations. We therefore decided to exclude SGLang from our comparisons as these were not directly comparable.
In the filtered results, we found SGLang’s performance was slightly slower than vLLM in terms of TPS, and lower than the Baseten implementation for both throughput and latency.
Math 500 Dataset (complicated mathematical reasoning)
This is from the HuggingFaceH4/MATH-500 dataset, also used in the DFlash research paper.
In terms of throughput (higher is better):
| Setting | Speedup in TPS | TPS (mean) | TPS (median) | TPS (p95) |
|---|---|---|---|---|
| Baseline TRT-LLM (no SpecDec) | 1.00x | 228.04 | 228.31 | 232.18 |
| Baseten EAGLE (best setting) | 2.05x | 468.52 | 468.39 | 521.40 |
| Baseten DFlash (best setting) | 3.05x | 694.91 | 697.78 | 840.69 |
And latency (lower is better):
| Setting | Speedup in latency | Latency (mean, s) | Latency (median, s) | Latency (P95, s) |
|---|---|---|---|---|
| Baseline TRT-LLM (no SpecDec) | 1.00x | 12.10 | 13.50 | 13.78 |
| Baseten EAGLE (best setting) | 2.01x | 6.02 | 6.36 | 7.44 |
| Baseten DFlash (best setting) | 2.94x | 4.12 | 4.29 | 5.63 |
Diverse prompts (NVIDIA’s Nemotron post-training dataset)
This benchmark comes from the nvidia/Nemotron-Post-Training-Dataset-v2 dataset and tests science, math, coding, and general chat abilities.
First, throughput (higher is better):
| Setting | Speedup in TPS | TPS (mean) | TPS (median) | TPS (p95) |
|---|---|---|---|---|
| Baseline TRT-LLM (no SpecDec) | 1.00x | 226.58 | 226.87 | 232.64 |
| Baseten EAGLE (best setting) | 1.91x | 433.75 | 436.31 | 505.81 |
| Baseten DFlash (best setting) | 2.25x | 510.39 | 516.67 | 666.72 |
And latency (lower is better):
| Setting | Speedup latency | Latency (mean, s) | Latency (median, s) | Latency (p95, s) |
|---|---|---|---|---|
| Baseline TRT-LLM (no SpecDec) | 1.00x | 11.45 | 13.59 | 14.00 |
| Baseten EAGLE (best setting) | 1.92x | 5.95 | 6.63 | 7.77 |
| Baseten DFlash (best setting) | 2.25x | 5.09 | 5.37 | 6.96 |
How to train DFlash draft models
At Baseten, we also train DFlash draft models from scratch when the application calls for it. Training takes two inputs:
Input IDs
Target model hidden states
We sample random anchors to define the last accepted token. Everything before it is treated as context, and we pass the target model's hidden states for those tokens. For the block_size number of tokens starting at the anchor, we use the input IDs as targets and run the denoising step with standard cross-entropy loss. The embedding and lm_head are both frozen.
Since earlier tokens are more important in speculative decoding, we weight them higher: the token is weighted by for a decay parameter .
If you want to learn more about the Baseten Speculation Engine or use it for your own workloads, reach out to talk to our engineers!