
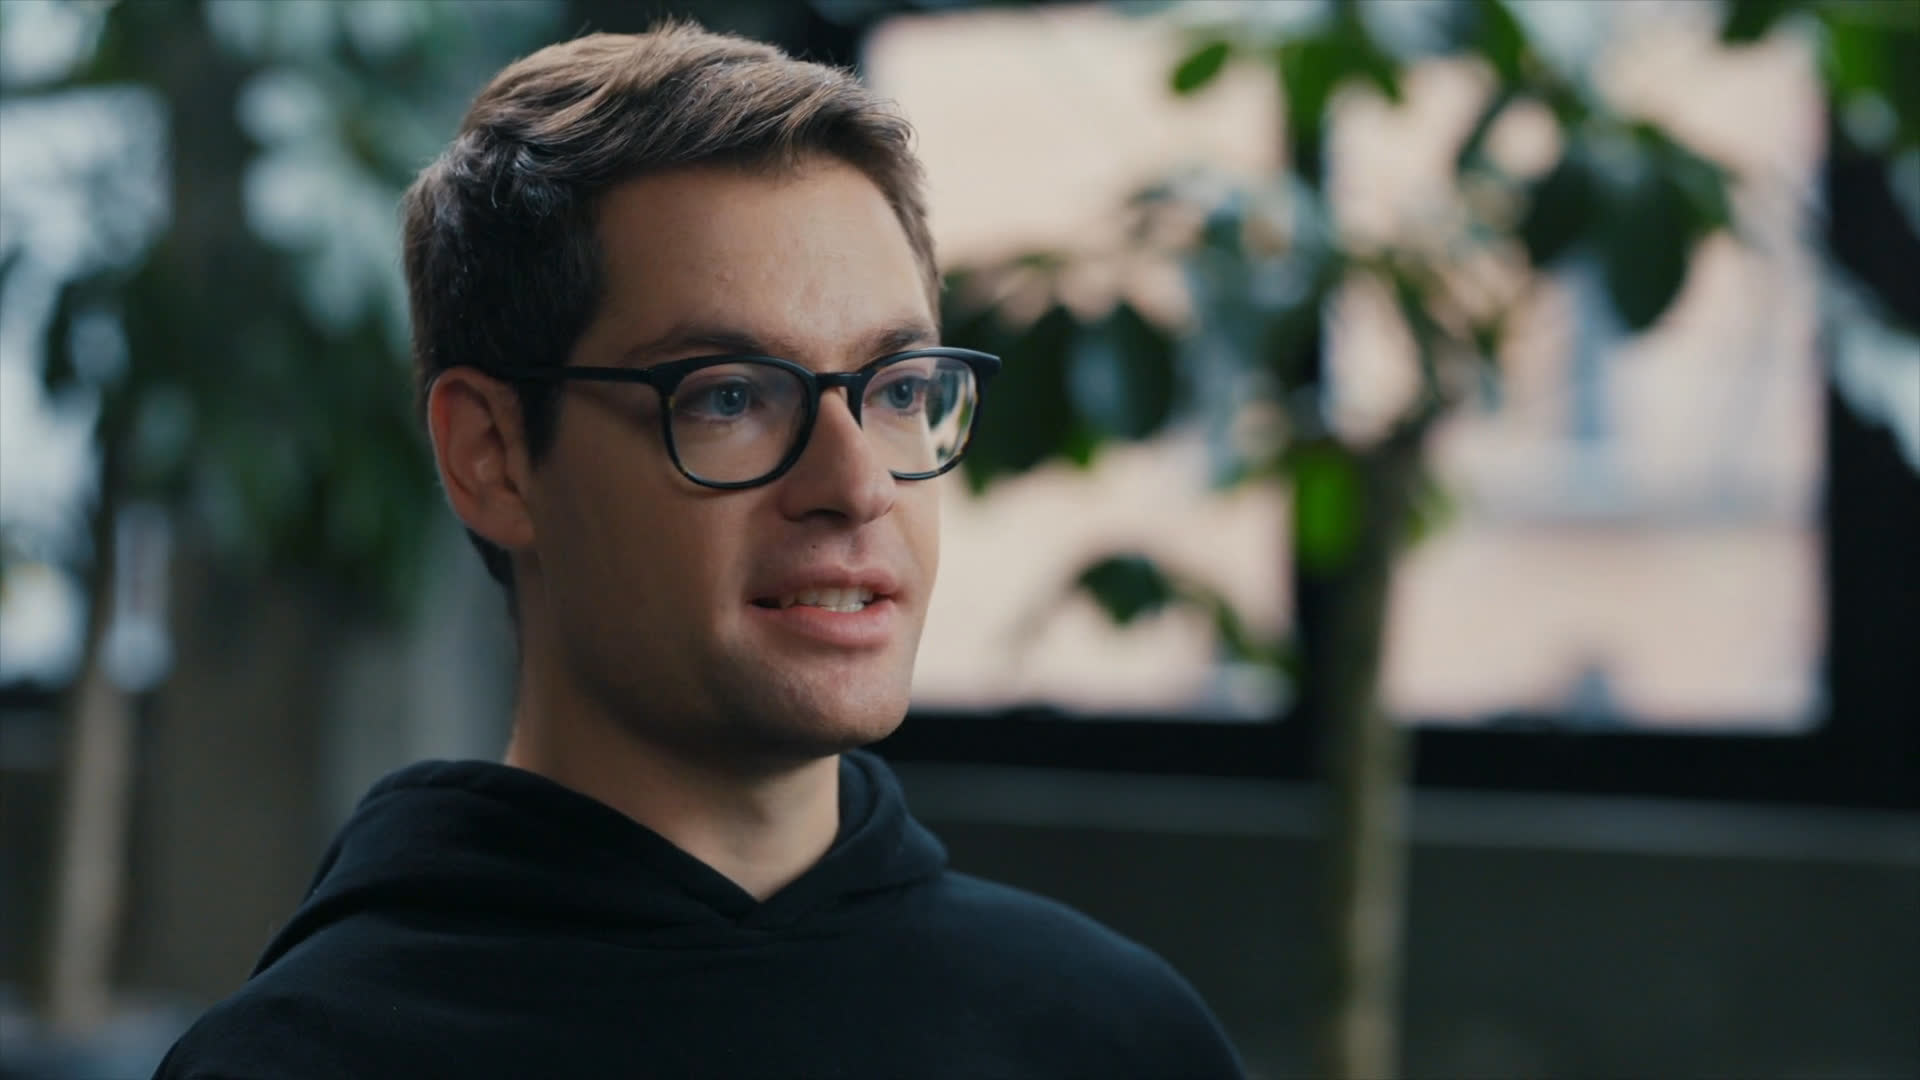
“Through the partnership with Baseten, we have the ability to serve different types of models, which means that my team can really focus on the ones that are the best fit.”

Please rotate your device
To continue exploring this website, please rotate your device to a vertical orientation
saved via model training
lower latency with AI meeting notes
cost-savings vs. closed-source
lower latency per image
“Through the partnership with Baseten, we have the ability to serve different types of models, which means that my team can really focus on the ones that are the best fit.”
“Baseten gives Canva the confidence to launch AI features to hundreds of millions of people, knowing that the capacity will be there when we need it.”
“Our customers really care about speed, reliability and the ability to deploy custom fine tuned models for financial services. Baseten met all three criteria far and above all the competition.”
“Baseten lets us productionize our models in days, not months.”
“We generate millions of images a day on Baseten for our 70+ million users with ultra-low latency and high throughput.”
“Baseten Loops helps us test new ideas in multi-turn agentic RL with on-demand capacity and a flexible training SDK. We can experiment with open-weight models while keeping control over our training logic.”
OpenEvidence partners with Baseten for their inference infrastructure to focus on what they do best: making exceptional tools for physicians.
Writer, the leading full-stack generative AI platform, launched new industry-specific LLMs for medicine and finance. Using TensorRT-LLM on Baseten, they increased their tokens per second by 60%.
By partnering with Baseten, Zed achieved 45% lower latency, 3.6x higher throughput, and 100% uptime for their Edit Prediction feature.
Rime AI chose Baseten to serve its custom speech synthesis generative AI model and achieved state-of-the-art p99 latencies with 100% uptime in 2024.
Wispr Flow runs fine-tuned models with Baseten to provide seamless dictation across every application.
With Baseten handling inference, Gamma's lean team stays focused on building a product users love.
Superhuman cut P95 latency by 80% across dozens of custom embedding models in just one week after adopting Baseten Embedding Inference.
Latent Health uses Baseten to power fast, reliable clinical AI.
With fast, reliable inference from Baseten, OpenCode keeps developers in their flow.
With Baseten, Praktika delivers <300 milliseconds latency empowering language learners worldwide with a seamless conversational and learning experience.
Oxen AI is a platform focused on helping companies accelerate the path from raw datasets to fine-tuned, production-ready AI models. They partner with Baseten to handle the infrastructure layer while they innovate on the customer facing side.
Scaled Cognition cut latency 40% and hit <120 ms TTFT with Baseten’s hybrid autoscaling—powering ultra-fast, enterprise-grade agentic workflows.
With Baseten, Patreon deployed and scaled the open-source foundation model Whisper at record speed without hiring an in-house ML infra team.
How Sully.ai addressed their latency, cost and quality challenges by transitioning its Inference Stack to open-source models running on Baseten.
OpenEvidence trains their custom models on Baseten Training, utilizing key features such as code customizability, on-demand compute, and one-click deploys to production inference.
World Labs is building the optic nerve of AI
Posit ships context-aware AI code completions for RStudio, powered by Baseten's fast, flexible inference.
Hebbia powers real-time financial intelligence for top institutions with Baseten's low-latency inference infrastructure.
OpenCode partnered with Baseten to power Zen, their model gateway for coding agents, achieving 5x faster inference, sub-second TTFT, and a 33% cost reduction while scaling from 40k to 10M monthly active users.
When Poolside set out to launch their Laguna model family to the world, they needed more than a hosting provider. They needed a partner who could move as fast as they did. Baseten deployed a full production inference platform for them in just 7 weeks.
EliseAI is the domain expert in AI-powered housing and healthcare and tackling some of the hardest operational problems in the economy. By partnering with Baseten Applied Research, EliseAI now owns the intelligence powering its product.
Speechify synthesizes 161B+ characters per month for 60M+ users. With Baseten, Speechify cut costs by 44%, p99 latency by 30-50%, and got 4.5x faster cold starts.
SpeechifyAI is the developer arm of Speechify, the world's leading voice AI platform serving more than 50 million users, with APIs for text-to-speech, voice agents, and conversational AI.
Parallel powers high-throughput agentic web research with Baseten's throughput-optimized inference and training-to-deployment loop.
You.com enables you to search the web, extract clean content, and generate grounded answers for Agents and LLMs.
Notion built AI Meeting Notes with a custom, streaming transcription and diarization pipeline on Baseten and cut costs by 50%
Magicare AI is the AI-native operating system for post-acute care, agentically automating healthcare administration and clinical services for nursing homes, behavioral health, and home health. Magicare reduces admission decisions from 30-60 minutes to <1 minute and automates authorizations, reimbursement, and compliance.
Mirendil runs rollouts on Baseten's RL stack and global fleet of clusters.
Baseten Loops provides managed infrastructure for fine-tuning models through an API, with support for supervised fine-tuning, reinforcement learning, and long-context workloads.
New research with Harvey shows how recursive language model harnesses and post-training can improve AI performance on complex M&A diligence.
Tell us what you're building. We'll partner with you on your workload, performance goals, and path to production.