Please rotate your device
To continue exploring this website, please rotate your device to a vertical orientation

From managed training to your own custom code.

Loops
Post-train open models through our training SDK, without provisioning or reserving GPUs.
Run SFT or RL with your own data and training logic. Support for long sequence lengths, async RL, and direct deployments to inference. Available for serverless multi-tenant or dedicated single-tenant training.

Training Jobs
Run your own training code on managed GPUs, from single-node experiments to large, multi-node jobs.
Bring your preferred framework for full fine-tuning or custom training workloads. Baseten handles GPU provisioning and checkpoint storage, with SSH workstation access to debug.

RL Rollouts
Bring your existing trainer and we help you scale your samplers across a global fleet.
We have the fastest delta weight syncs in the world. Baseten manages a global sampling fleet and loads updated weights in a few seconds. Used by frontier labs to scale up their rollouts.
Frontier RL with Baseten Loops
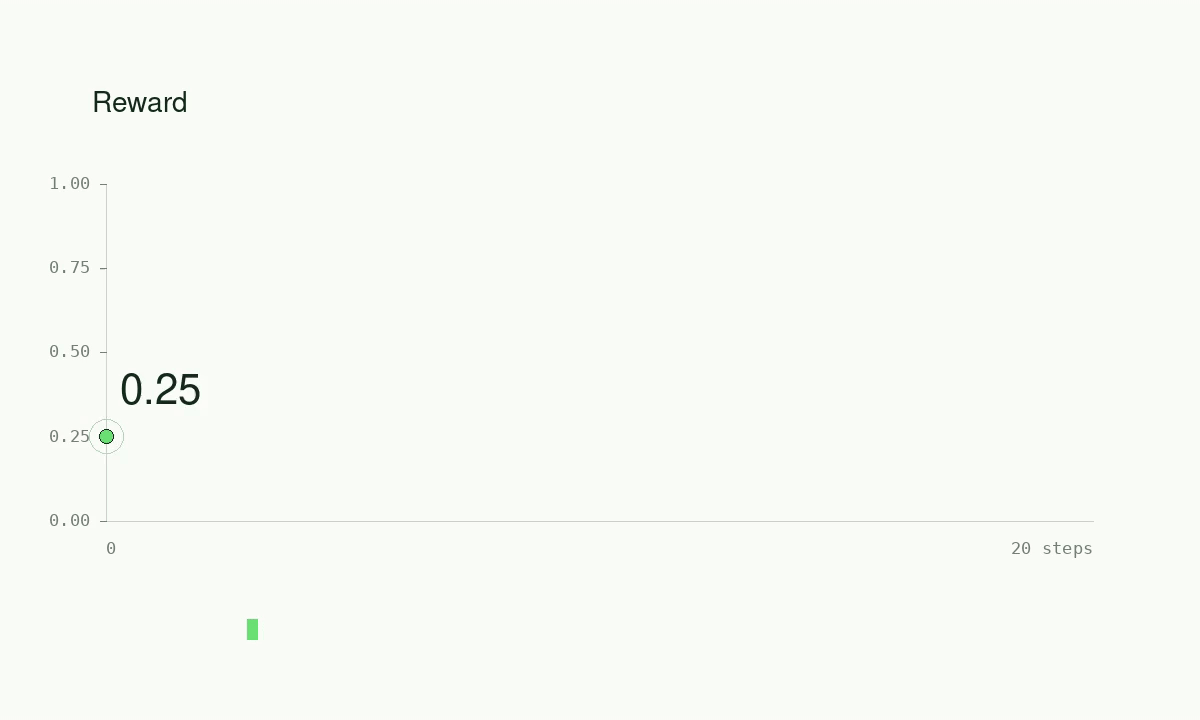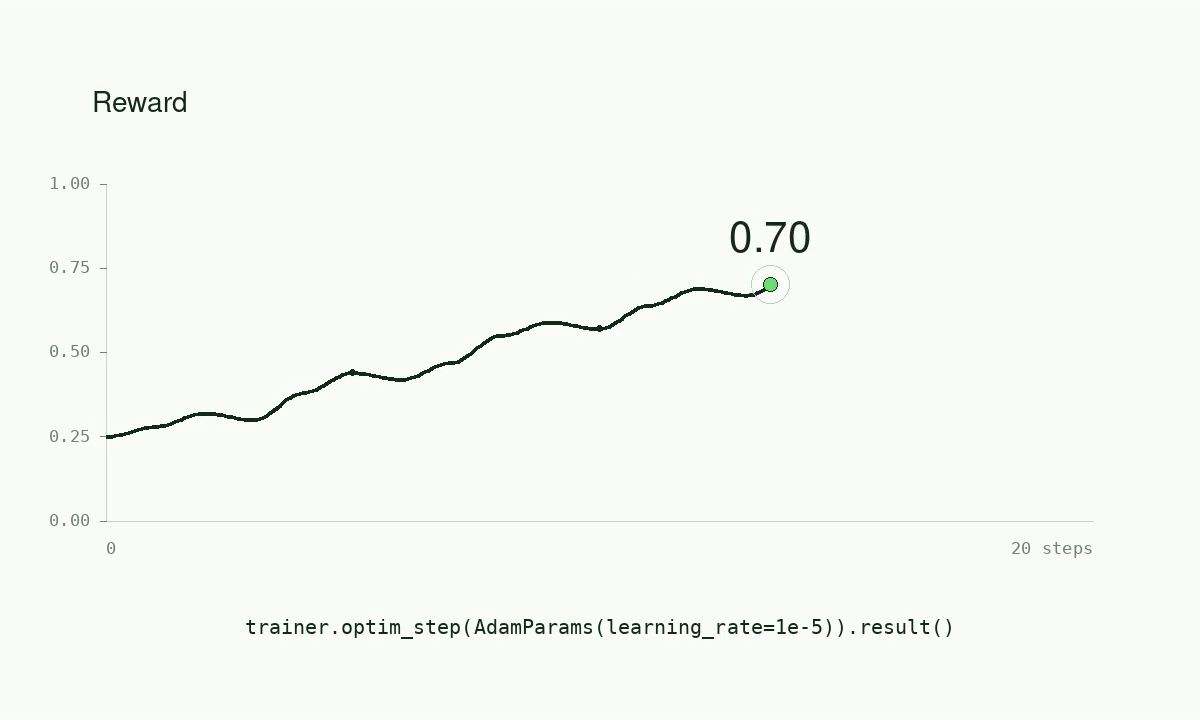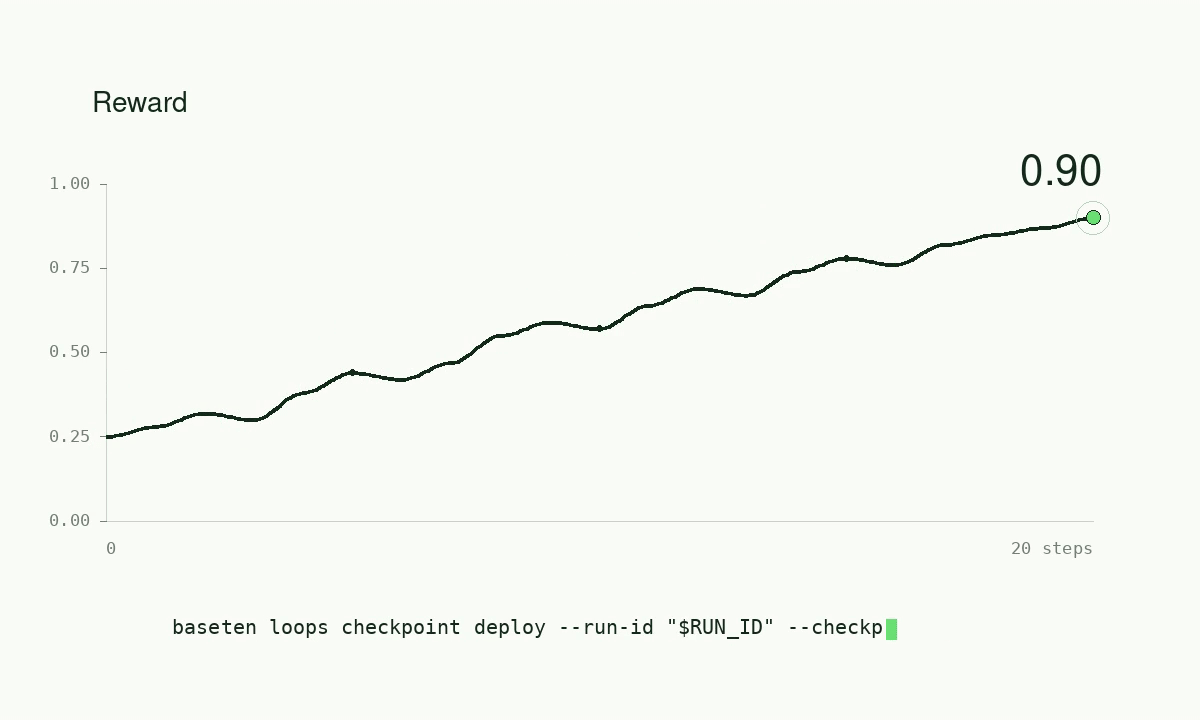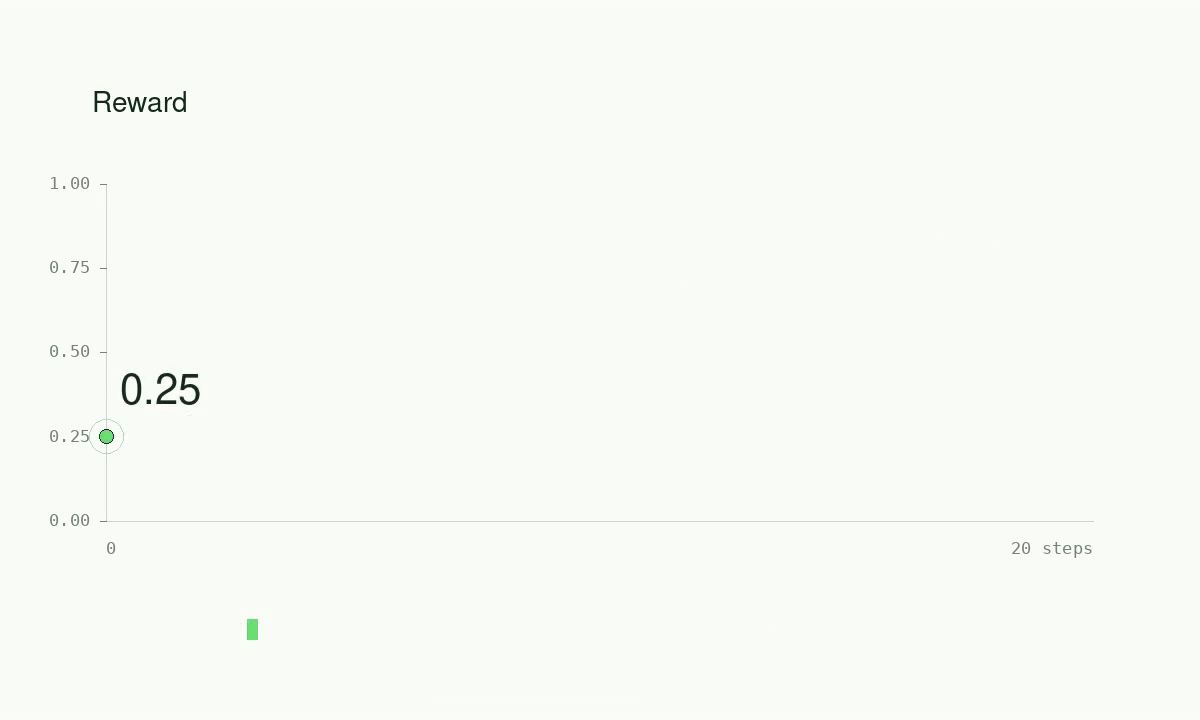
You control the data, rewards, and loss functions. Baseten manages the infra, trainer and sampler fleets, live weight syncs, and deployable checkpoints.
- 01
Train frontier models at scale
Train 2T+ models at 256K+ sequence length, with support for Qwen, Kimi, GLM, DeepSeek, Muse, Gemma, and Nemotron.
- 02
Train and deploy on one platform
Deploy models trained with Loops directly to Baseten Dedicated Inference. The model that you train is the model that you serve.
- 03
Get started with our cookbook recipes
Run multi-turn training, set up async RL, visualize your rollouts and reward metrics, and more – out of the box.
Your Training. Your IP.
You keep full ownership of your models, training scripts, data, and artifacts when using Baseten Training or working with our Applied Research Team.
Enterprise Security
Baseten is zero data retention by default. Configure your training and inference in specific data residency zones and HIPAA compliant clusters.
Our applied researchers embed alongside your team to train custom models.
Scope
We work with you to define the task and the success metrics that matter.
Design
We design the environment and rewards for your use case.
Train and iterate
We build the data pipeline and iterate against real evals.
Ship
Your model goes to a fast, reliable production endpoint on Baseten.

How to start training your custom model on the Baseten platform.
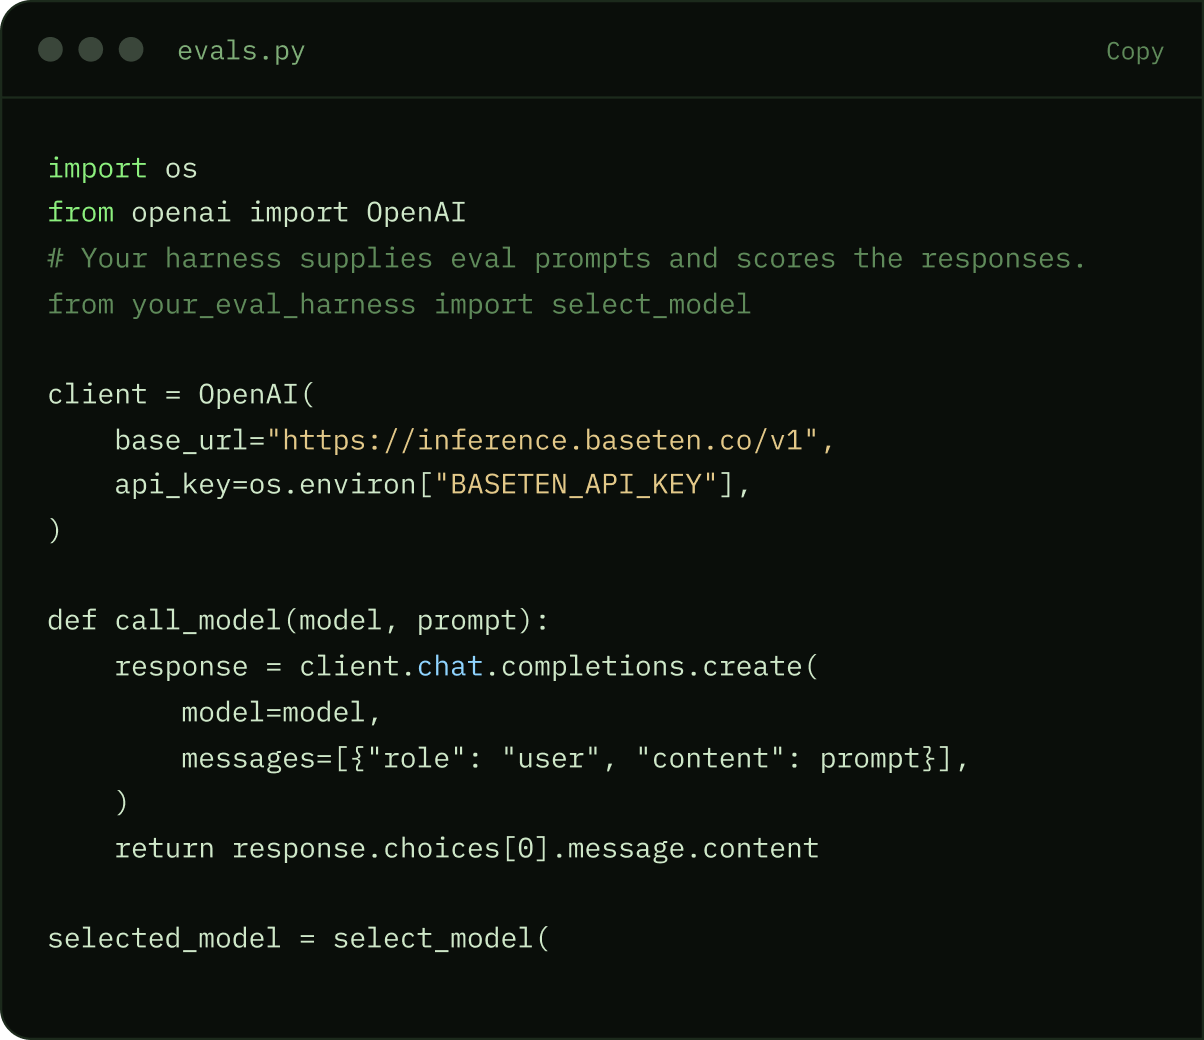
Evaluate the latest open frontier models to see which ones perform best on your task and are great candidates to post-train.
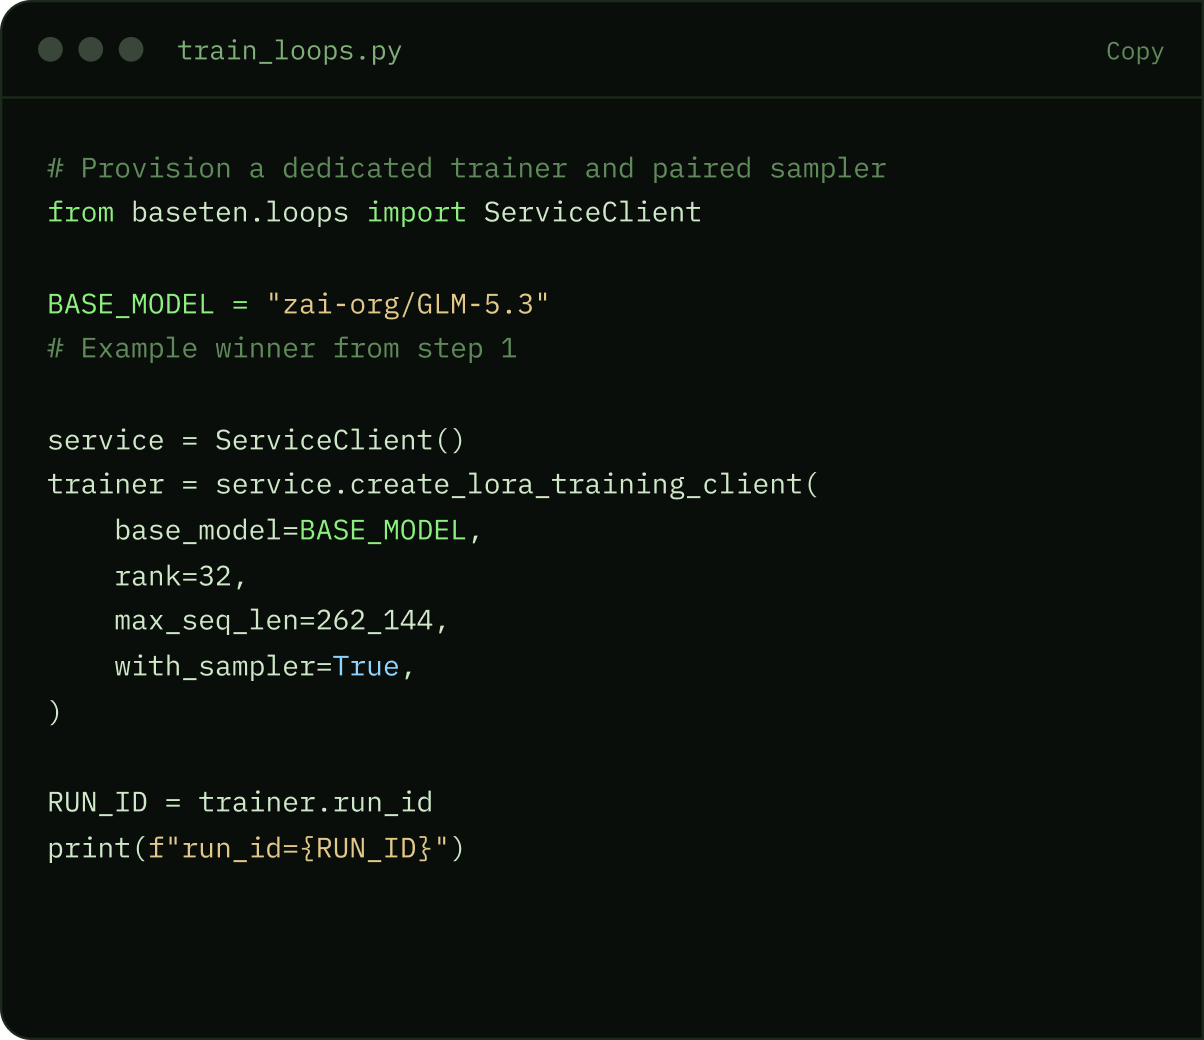
Use the Loops SDK to choose a base model, context length, and LoRA rank. Baseten provisions the dedicated trainer for SFT and paired sampler for RL.
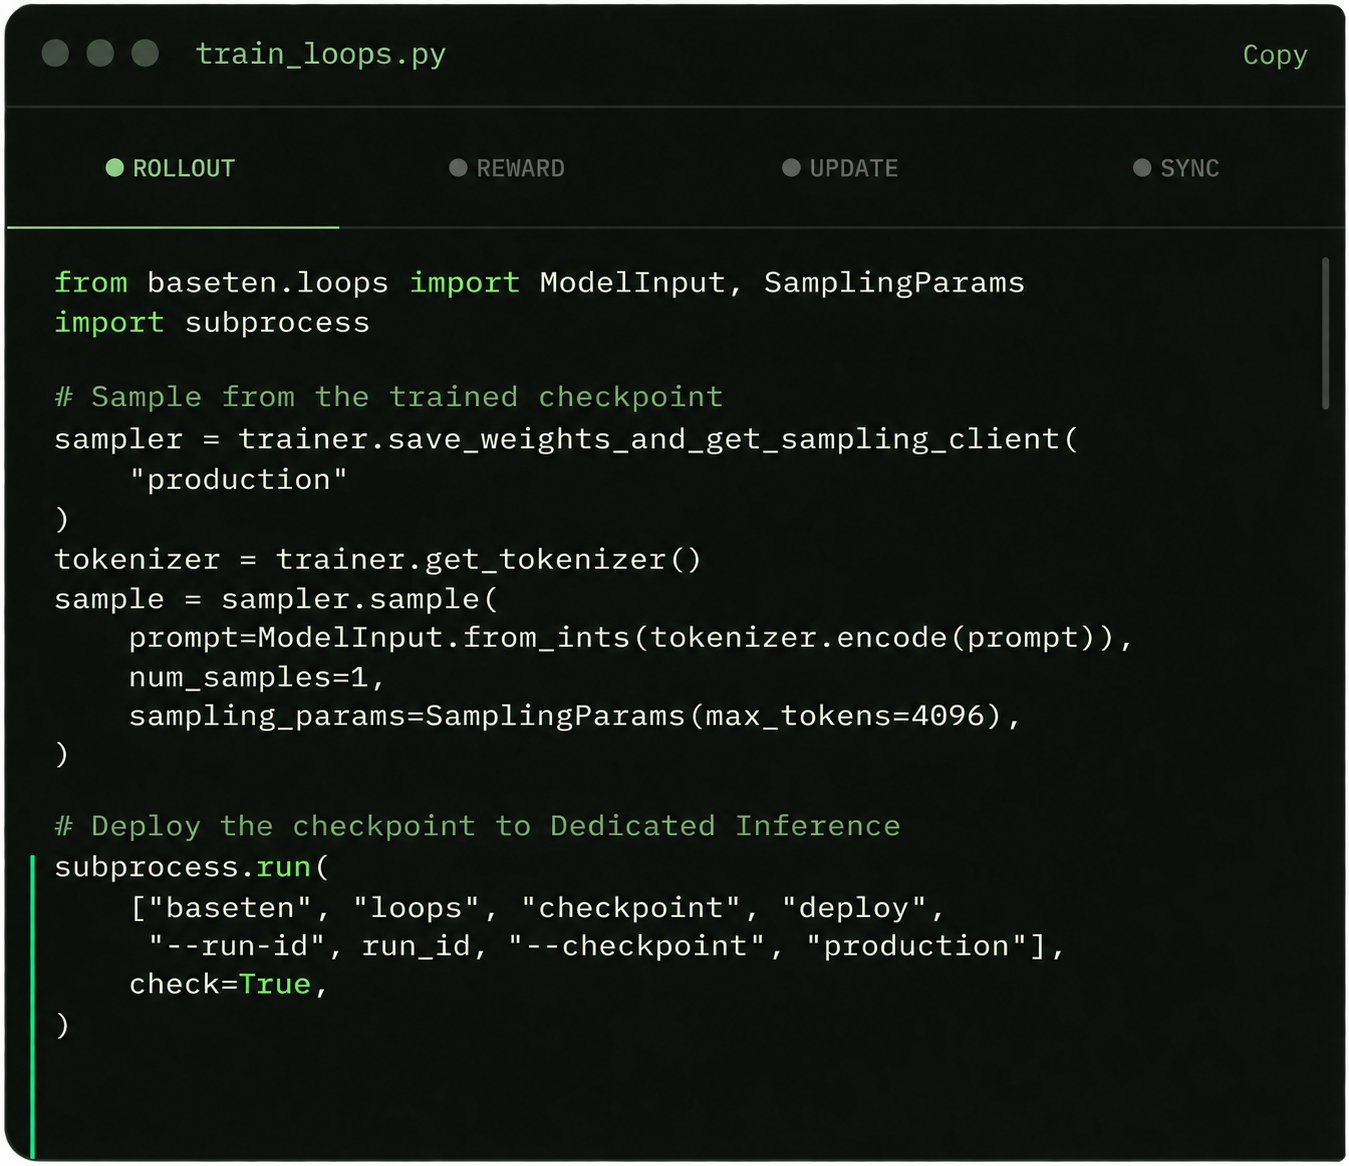
Deploy your trained model to a dedicated endpoint on the Baseten Inference Stack. Serve production traffic with our fast, reliable inference.

Train your own custom model that beats the frontier.