Please rotate your device
To continue exploring this website, please rotate your device to a vertical orientation

Obsessively engineered at every layer.
Research-backed performance
Speed that feels natural takes unnatural obsession. Our Model APIs are optimized at every layer of the stack: routing, batching, caching, speculative decoding, kernel-level optimizations and more. We go beyond open-source frameworks with proprietary research and techniques for every use case.
Consistent quality
Our Model APIs are engineered for consistent, transparent quality. Every model is evaluated against the lab’s published benchmarks before launch and runs at the precision we publish, with no silent downgrades. Our custom quantizations preserve more quality than off-the-shelf methods.
Custom capabilities
Open weights are just the starting point. Our post-training team adds additional capabilities to original releases to ensure you get the latest intelligence without tradeoffs. From adding vision capabilities to LLMs to custom training the most intelligent decision models available, all served on Model APIs.
Kimi K3
Moonshot AI/Kimi K3
P50 TPS
50
P50 TTFT
6.5
DeepSeek V4.1 Flash 1017
DeepSeek/DeepSeek V4.1 Flash 1017
P50 TPS
250
P50 TTFT
0.13s
DeepSeek V4.1 Flash 1017 Fast
DeepSeek/DeepSeek V4.1 Flash 1017 Fast
P50 TPS
1000
P50 TTFT
0.85s
GLM-5.3
Z AI/GLM-5.3
P50 TPS
300
P50 TTFT
0.2s
GLM-5.3-Flash
Z AI/GLM-5.3-Flash
P50 TPS
120
P50 TTFT
0.25s
mammoth-1
Base Labs/mammoth-1
P50 E2E Latency
0.65s

elephant-1
Base Labs/elephant-1
P50 E2E Latency
0.5s
Unlock frontier models in one line of code.
Our APIs are compatible with OpenAI and Anthropic SDKs, so switching takes one line of code. Get frontier open-source models at up to 3x lower cost, without changing the way you work.
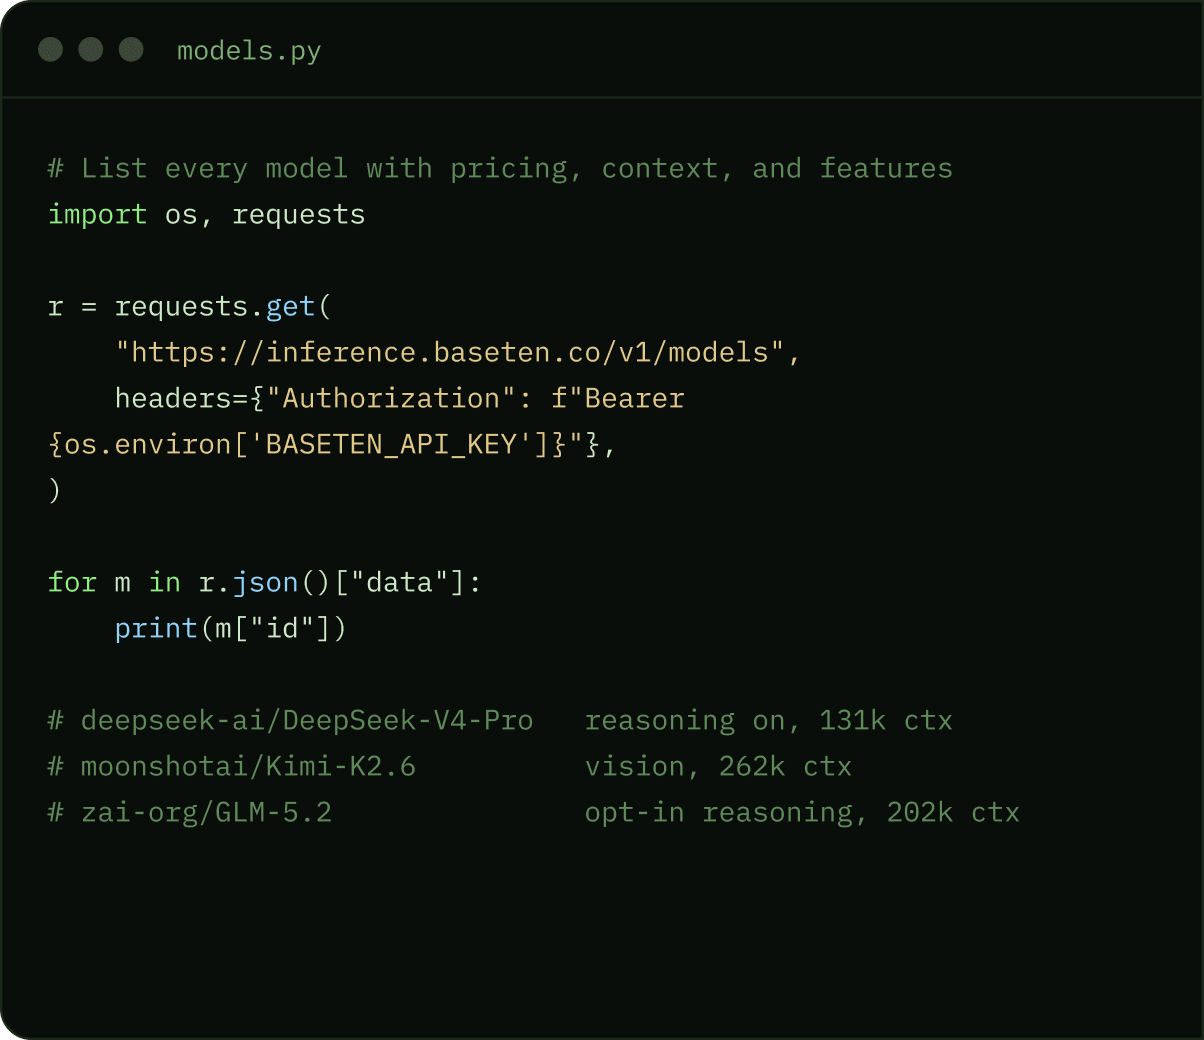
Frontier open-source LLMs, optimized for performance, scale, and reliability. Our training team also adds multimodal capabilities through post-training, so you get more than the off-the-shelf weights.
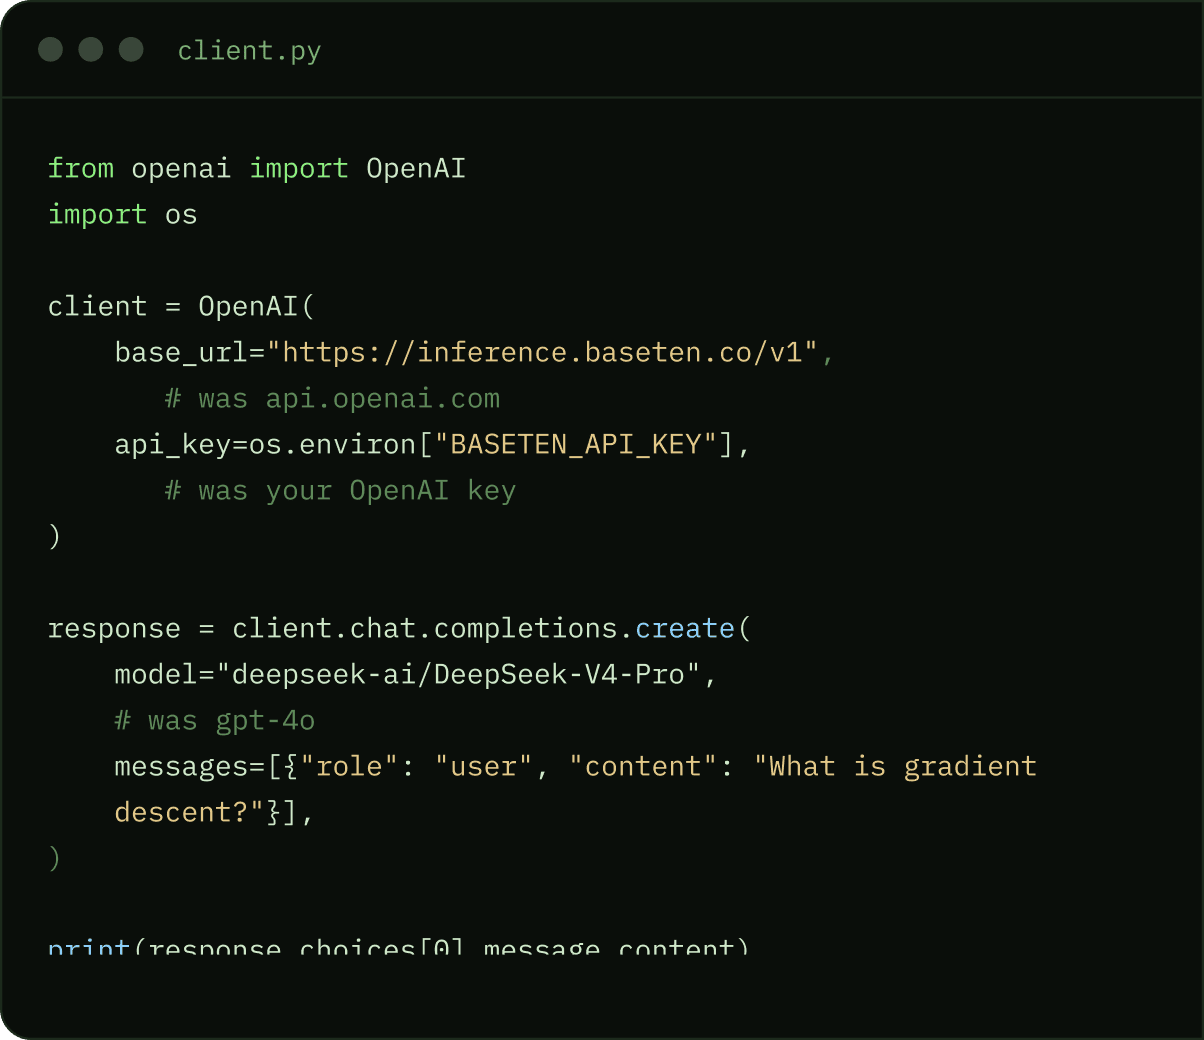
Compatible with the OpenAI and Anthropic APIs. Keep your SDK and change three things: the base URL, your API key, and the model slug. Configure reasoning, vision, tool calling, structured outputs, and JSON mode to fit each task.
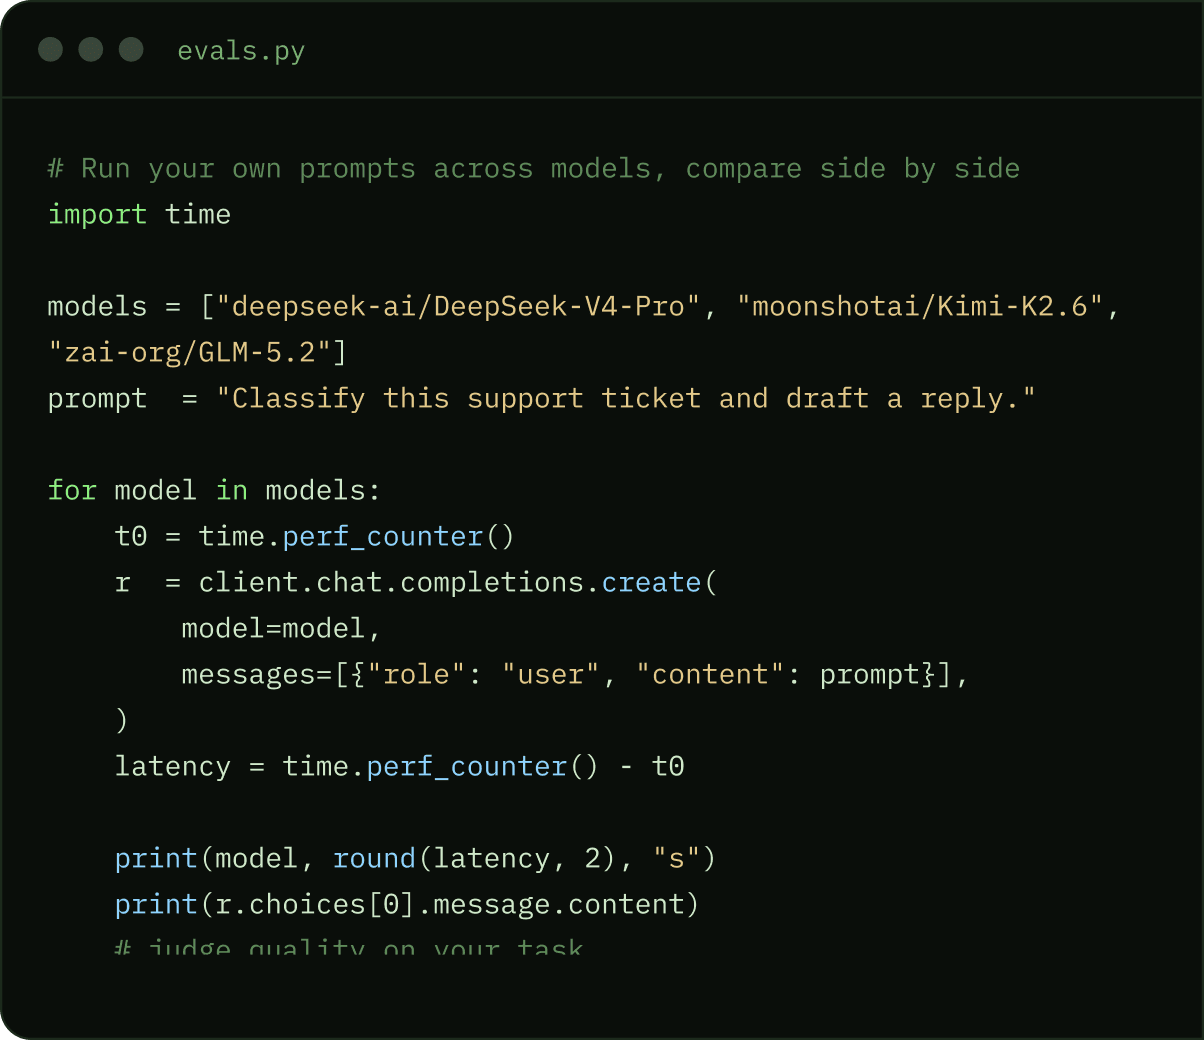
On Baseten, open-source models can be up to 4x faster and 5x more cost-effective than closed-source alternatives. Compare models side by side on your own prompts, so you ship the one that performs best on your task.
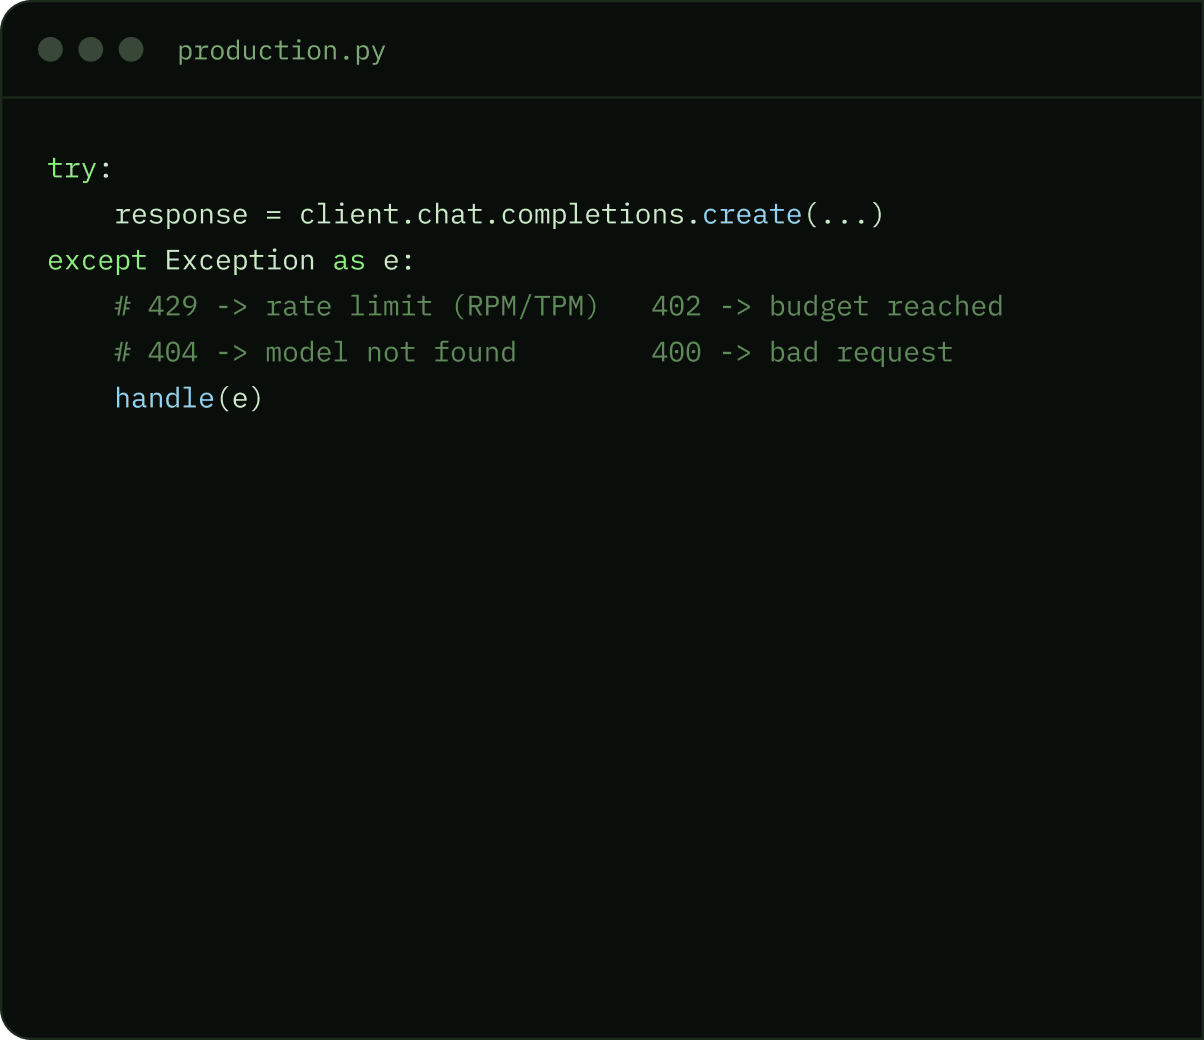
Set per-model rate limits and track spend by API key, user, or model, so you always know who is driving usage. Budgets can alert you or hard-stop Model API spend before a runaway job does damage.


As new models comes out, we want to test, optimize, and deploy it into production on day zero. Baseten lets us do that.
, Engineering Lead
- Interface Engineering
- <80ms
- Throughput
- 3x
Build at the pace of the frontier. Scale with enterprise confidence.

Zero data retention
Model APIs have zero data retention by default, which means your prompts and outputs are never stored or used for training.

99.9% uptime
Our APIs run on a unified compute platform spanning 20+ clouds. Your workloads get near-limitless scale and high uptime.

Regional data residency
Keep inference within US-based infrastructure to meet your compliance requirements without changing how you build.

Day zero access
We partner with leading labs on every major model drop, so you get production-ready models on day zero and ship first.

Controlled quantization
Models run at the precision we publish, with no silent downgrades, so output quality stays consistent as you scale.

Thoughtful deprecation
Get ample notice and a clear migration path before any model is retired, so you’re never forced into a rushed switch.
Ship with the best open models