Please rotate your device
To continue exploring this website, please rotate your device to a vertical orientation

Fast, reliable inference with global capacity and expert support.
99.99% uptime
Stay online through traffic spikes, GPU shortages, and cloud disruptions. Baseten’s multi-cloud capacity and failover keep you up when a single provider or region is constrained.
20+ cloud providers
Multi-cloud capacity (MCM) pools siloed resources into a global GPU supply, giving access to capacity for fast inference under any load without managing every cloud yourself.
24/7 support
Partner with the engineers who built the platform and serve as an extension of your team - helping you launch, optimize, troubleshoot, and scale with expert support at every step.
Built around your p99 target
We benchmark your production workload, identify latency and throughput bottlenecks, and optimize the model and serving stack for your p99 target.

Deploy, scale, and optimize any model.
Open, closed, and fine-tuned models run with custom performance optimizations on the Baseten Inference Stack.
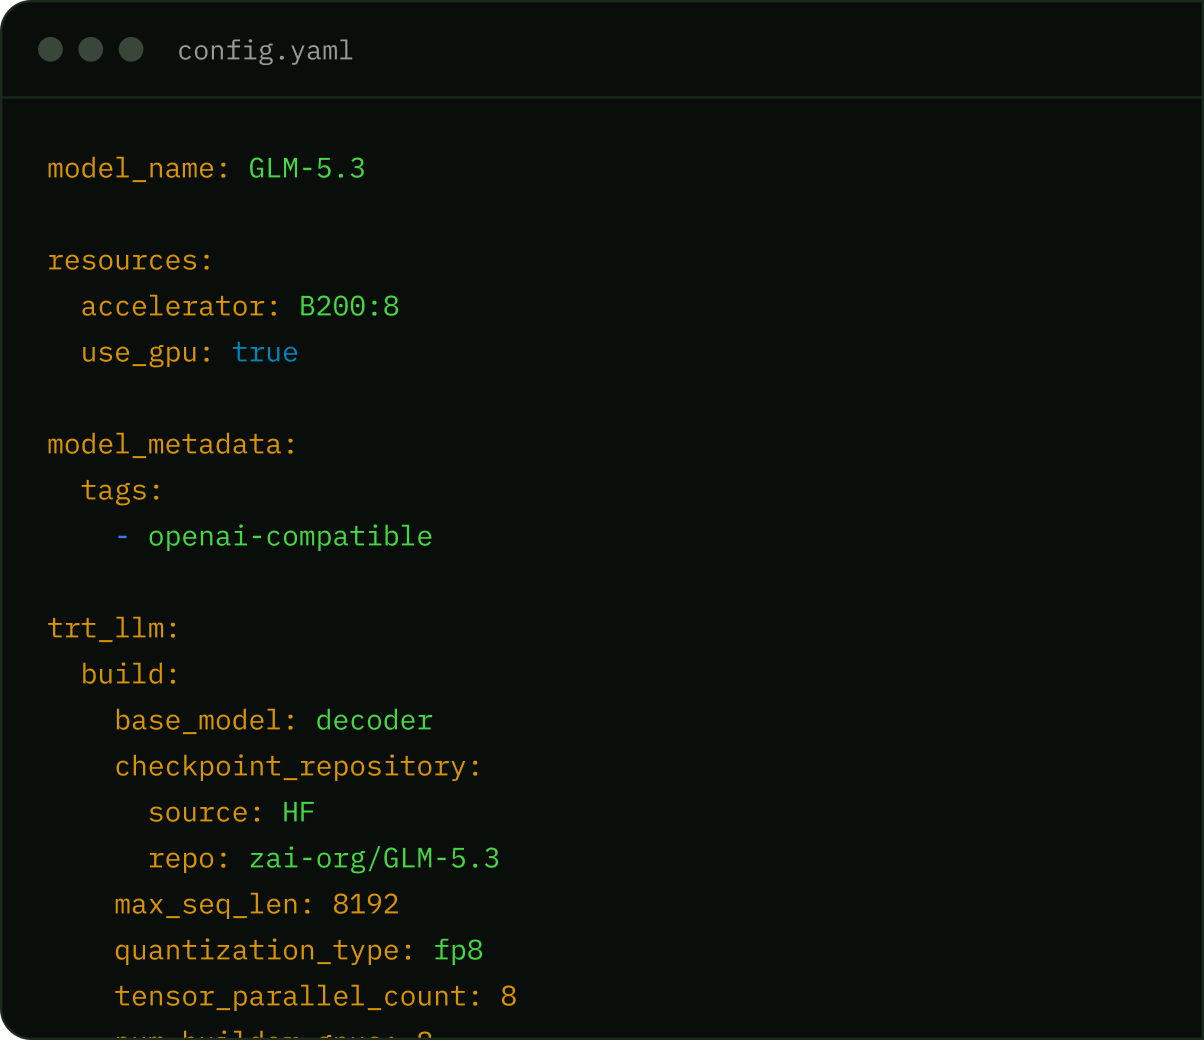
Go from model weights or a custom Docker container to a production-ready API endpoint in minutes. Deploy hundreds of models from our Model Library — or checkpoints from Baseten Training — with a single click.
Baseten’s autoscaler matches replicas to demand, drawing on compute across 20+ clouds while respecting your cloud and geographic preferences. Scale with traffic, and pay only for what you use.
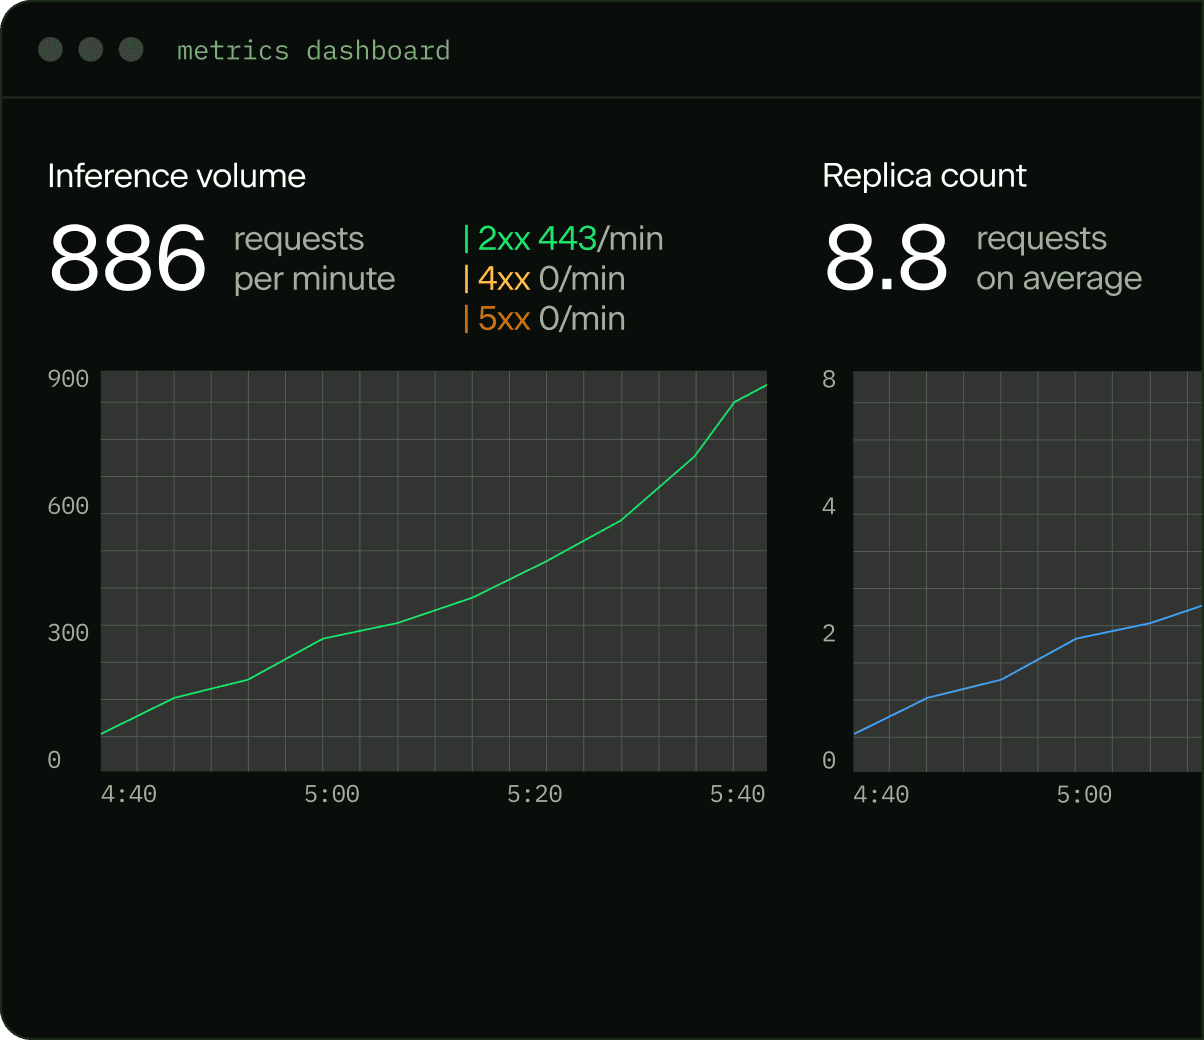
Baseten’s autoscaler matches replicas to demand, drawing on compute across 20+ clouds while respecting your cloud and geographic preferences. Scale with traffic, and pay only for what you use.
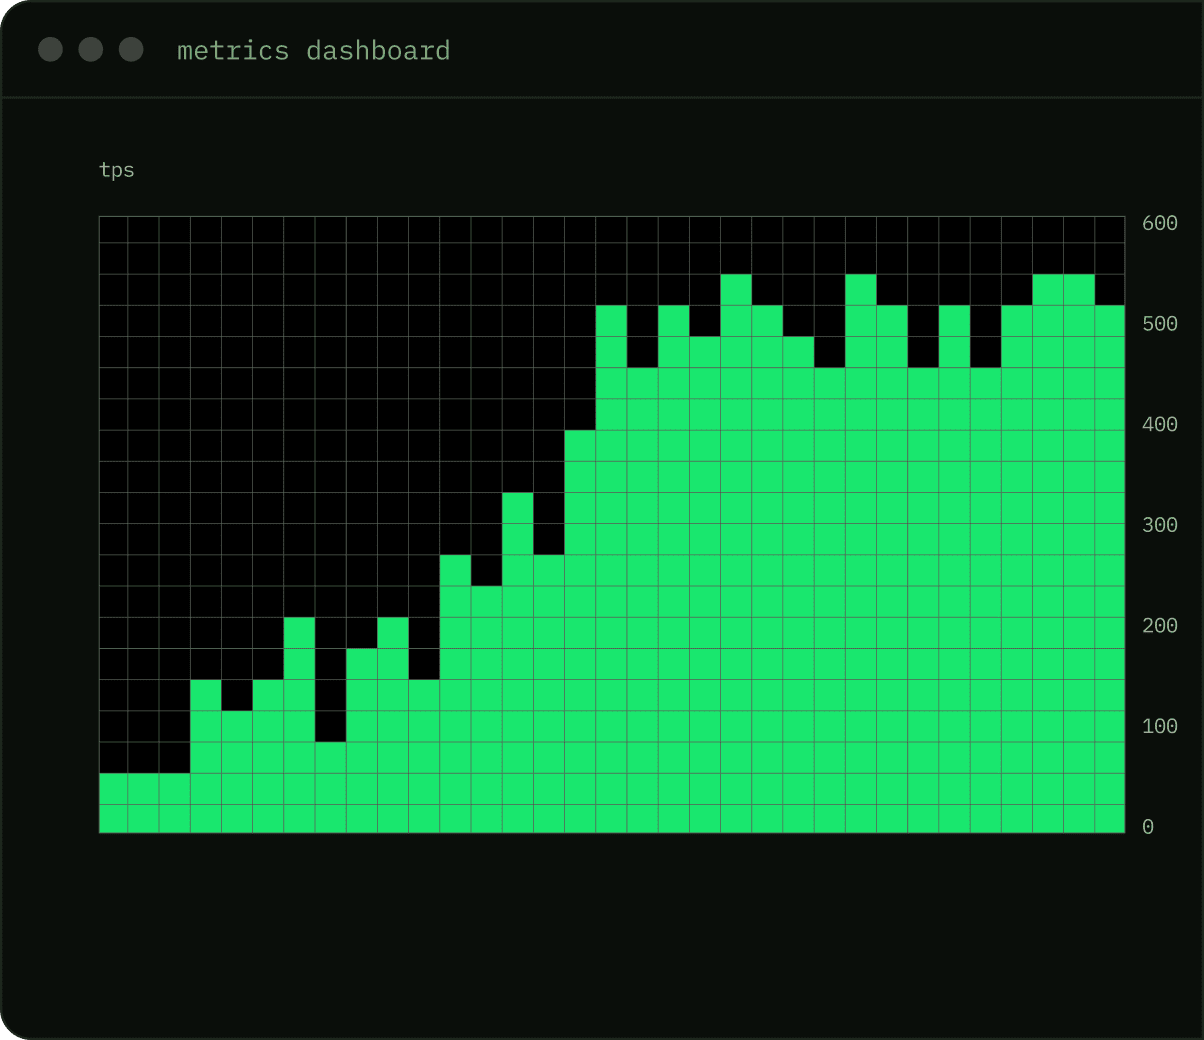
Put the latest model performance research to work. Our research team builds custom optimizations to lower inference latency and increase throughput — and contributes improvements back to open-source projects like TensorRT-LLM, SGLang, and vLLM.

Inference for teams pushing the frontier.

Speculative decoding
Accelerate generation with EAGLE, multi-token prediction, and n-gram speculation—matched to your model and tuned for your traffic.

Custom GPU kernels
Fused kernels, optimized memory access, and asynchronous compute reduce overhead and get more useful work from every GPU.

Scheduling and disaggregated serving
Tune request scheduling and, for eligible workloads, separate prefill and decode to reduce interference between prompt processing and token generation.

Quantization turned to your model
We select FP8 or FP4 quantization based on your model and GPU, then validate output quality with benchmarks and real inference samples.

KV-cache optimization
Reuse cached context and route requests to replicas that already hold it, reducing repeated prompt processing across agent loops, chat, and code generation.

Topology-aware parallelism
Distribute large models across GPUs and nodes using tensor and expert parallelism, tuned to hardware interconnects to reduce communication overhead.
- 01
Deploy for resilience
Coordinate serving capacity across clouds, with warm standby ready for production workloads.
- 02
Fail over automatically
When a GPU or cloud fails, MCM shifts traffic to standby capacity so requests keep flowing while the affected environment recovers.
- 03
Keep workloads in the right region
MCM uses region locking to help you meet location requirements across your deployments.
The right performance for every workload.

LLMs
The Baseten Inference Stack combines custom GPU kernels, batching, KV-cache optimization, and speculative decoding to reduce latency and increase throughput. We benchmark and tune the serving stack for your model and hardware.

Embeddings and rerankers
Tune runtimes and hardware for high-volume embedding and reranking requests, balancing response times and cost as you scale search, retrieval, and indexing.

Voice and audio models
From speech recognition to speech synthesis, audio models need serving tuned to their modality and latency demands. The Baseten Inference Stack uses runtimes and workload-aware optimizations for responsive voice experiences.
More power behind your models.